• A Coding Implementation to Automating LLM Quality Assurance with DeepEval, Custom Retrievers, and LLM-as-a-Judge Metrics

    We initiate this tutorial by configuring a high-performance evaluation environment, specifically focused on integrating the DeepEval framework to bring unit-testing rigor to our LLM applications. By bridging the gap between raw retrieval and final generation, we implement a system that treats model outputs as testable code and uses LLM-as-a-judge metrics to quantify performance. We move beyond manual inspection by building a structured pipeline in which every query, retrieved context, and generated response is validated against rigorous academic-standard metrics. Check out the FULL CODES here. import sys, os, textwrap, json, math, re from getpass import getpass print("🔧 Hardening environment (prevents common Colab/py3.12…
  • StepFun AI Introduce Step-DeepResearch: A Cost-Effective Deep Research Agent Model Built Around Atomic Capabilities

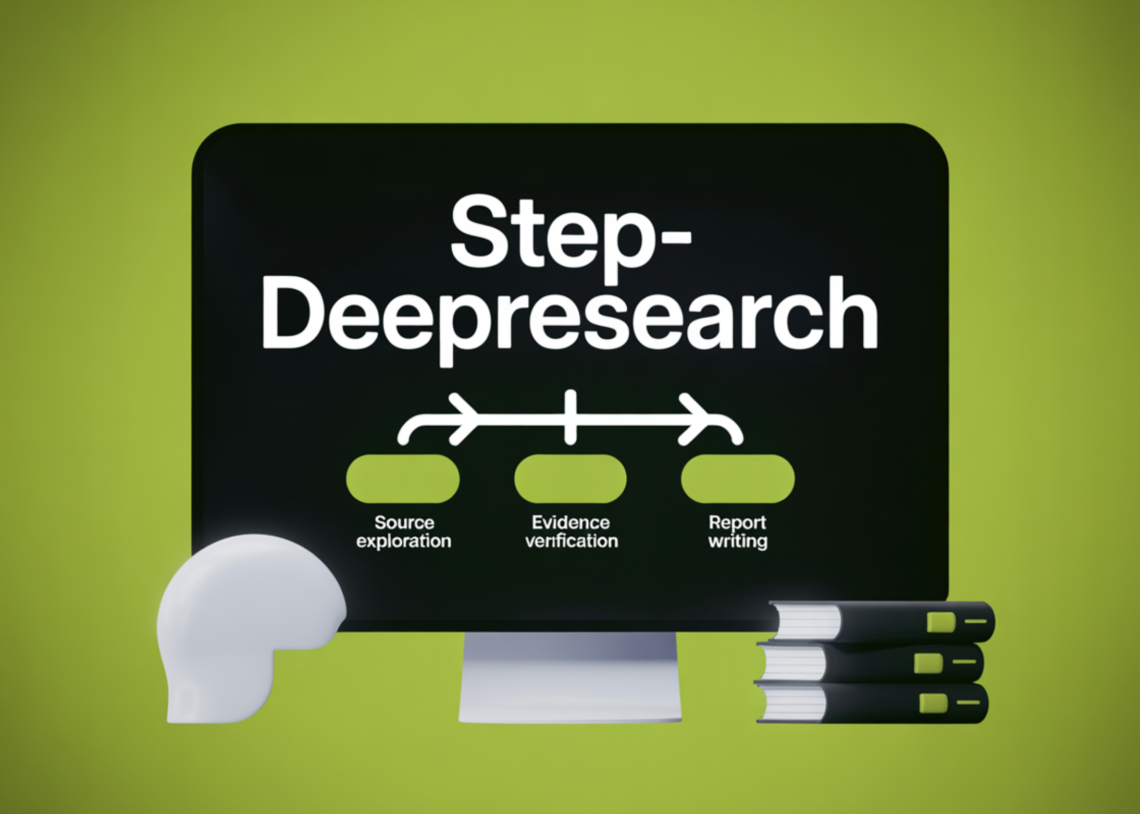
    StepFun has introduced Step-DeepResearch, a 32B parameter end to end deep research agent that aims to turn web search into actual research workflows with long horizon reasoning, tool use and structured reporting. The model is built on Qwen2.5 32B-Base and is trained to act as a single agent that plans, explores sources, verifies evidence and writes reports with citations, while keeping inference cost low. From Search to Deep Research Most existing web agents are tuned for multi-hop question-answering benchmarks. They try to match ground truth answers for short questions. This is closer to targeted retrieval than to real research. Deep…

  • How Machine Learning and Semantic Embeddings Reorder CVE Vulnerabilities Beyond Raw CVSS Scores

    def visualize_results(df, priority_scores, feature_importance): fig, axes = plt.subplots(2, 3, figsize=(18, 10)) fig.suptitle('Vulnerability Scanner - ML Analysis Dashboard', fontsize=16, fontweight="bold") axes[0, 0].hist(priority_scores, bins=30, color="crimson", alpha=0.7, edgecolor="black") axes[0, 0].set_xlabel('Priority Score') axes[0, 0].set_ylabel('Frequency') axes[0, 0].set_title('Priority Score Distribution') axes[0, 0].axvline(np.percentile(priority_scores, 75), color="orange", linestyle="--", label="75th percentile") axes[0, 0].legend() axes[0, 1].scatter(df['cvss_score'], priority_scores, alpha=0.6, c=priority_scores, cmap='RdYlGn_r', s=50) axes[0, 1].set_xlabel('CVSS Score') axes[0, 1].set_ylabel('ML Priority Score') axes[0, 1].set_title('CVSS vs ML Priority') axes[0, 1].plot([0, 10], [0, 1], 'k--', alpha=0.3) severity_counts = df['severity'].value_counts() colors = {'CRITICAL': 'darkred', 'HIGH': 'red', 'MEDIUM': 'orange', 'LOW': 'yellow'} axes[0, 2].bar(severity_counts.index, severity_counts.values, color=[colors.get(s, 'gray') for s in severity_counts.index]) axes[0, 2].set_xlabel('Severity') axes[0, 2].set_ylabel('Count') axes[0, 2].set_title('Severity Distribution') axes[0, 2].tick_params(axis="x",…

  • GitHub Releases Copilot-SDK to Embed Its Agentic Runtime in Any App

    GitHub has opened up the internal agent runtime that powers GitHub Copilot CLI and exposed it as a programmable SDK. The GitHub Copilot-SDK, now in technical preview, lets you embed the same agentic execution loop into any application so the agent can plan, invoke tools, edit files, and run commands as part of your own workflows. What the GitHub Copilot SDK provides The GitHub Copilot-SDK is a multi platform SDK for integrating the GitHub Copilot Agent into applications and services. It gives programmatic access to the execution loop that already powers GitHub Copilot CLI. Instead of building your own planner…

  • How an AI Agent Chooses What to Do Under Tokens, Latency, and Tool-Call Budget Constraints?

    In this tutorial, we build a cost-aware planning agent that deliberately balances output quality against real-world constraints such as token usage, latency, and tool-call budgets. We design the agent to generate multiple candidate actions, estimate their expected costs and benefits, and then select an execution plan that maximizes value while staying within strict budgets. With this, we demonstrate how agentic systems can move beyond “always use the LLM” behavior and instead reason explicitly about trade-offs, efficiency, and resource awareness, which is critical for deploying agents reliably in constrained environments. Check out the FULL CODES here. Copy CodeCopiedUse a different Browser import…

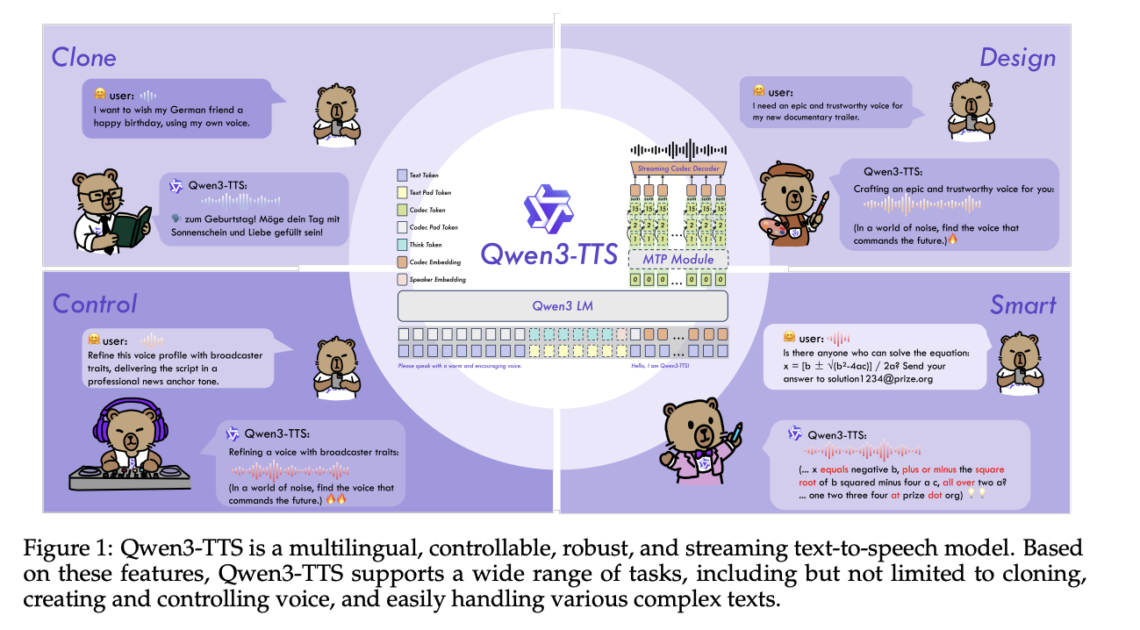
  • Qwen Researchers Release Qwen3-TTS: an Open Multilingual TTS Suite with Real-Time Latency and Fine-Grained Voice Control

    Alibaba Cloud’s Qwen team has open-sourced Qwen3-TTS, a family of multilingual text-to-speech models that target three core tasks in one stack, voice clone, voice design, and high quality speech generation. https://arxiv.org/pdf/2601.15621v1 Model family and capabilities Qwen3-TTS uses a 12Hz speech tokenizer and 2 language model sizes, 0.6B and 1.7B, packaged into 3 main tasks. The open release exposes 5 models, Qwen3-TTS-12Hz-0.6B-Base and Qwen3-TTS-12Hz-1.7B-Base for voice cloning and generic TTS, Qwen3-TTS-12Hz-0.6B-CustomVoice and Qwen3-TTS-12Hz-1.7B-CustomVoice for promptable preset speakers, and Qwen3-TTS-12Hz-1.7B-VoiceDesign for free form voice creation from natural language descriptions, along with the Qwen3-TTS-Tokenizer-12Hz codec. All models support 10 languages, Chinese, English, Japanese,…

  • Microsoft Releases VibeVoice-ASR: A Unified Speech-to-Text Model Designed to Handle 60-Minute Long-Form Audio in a Single Pass

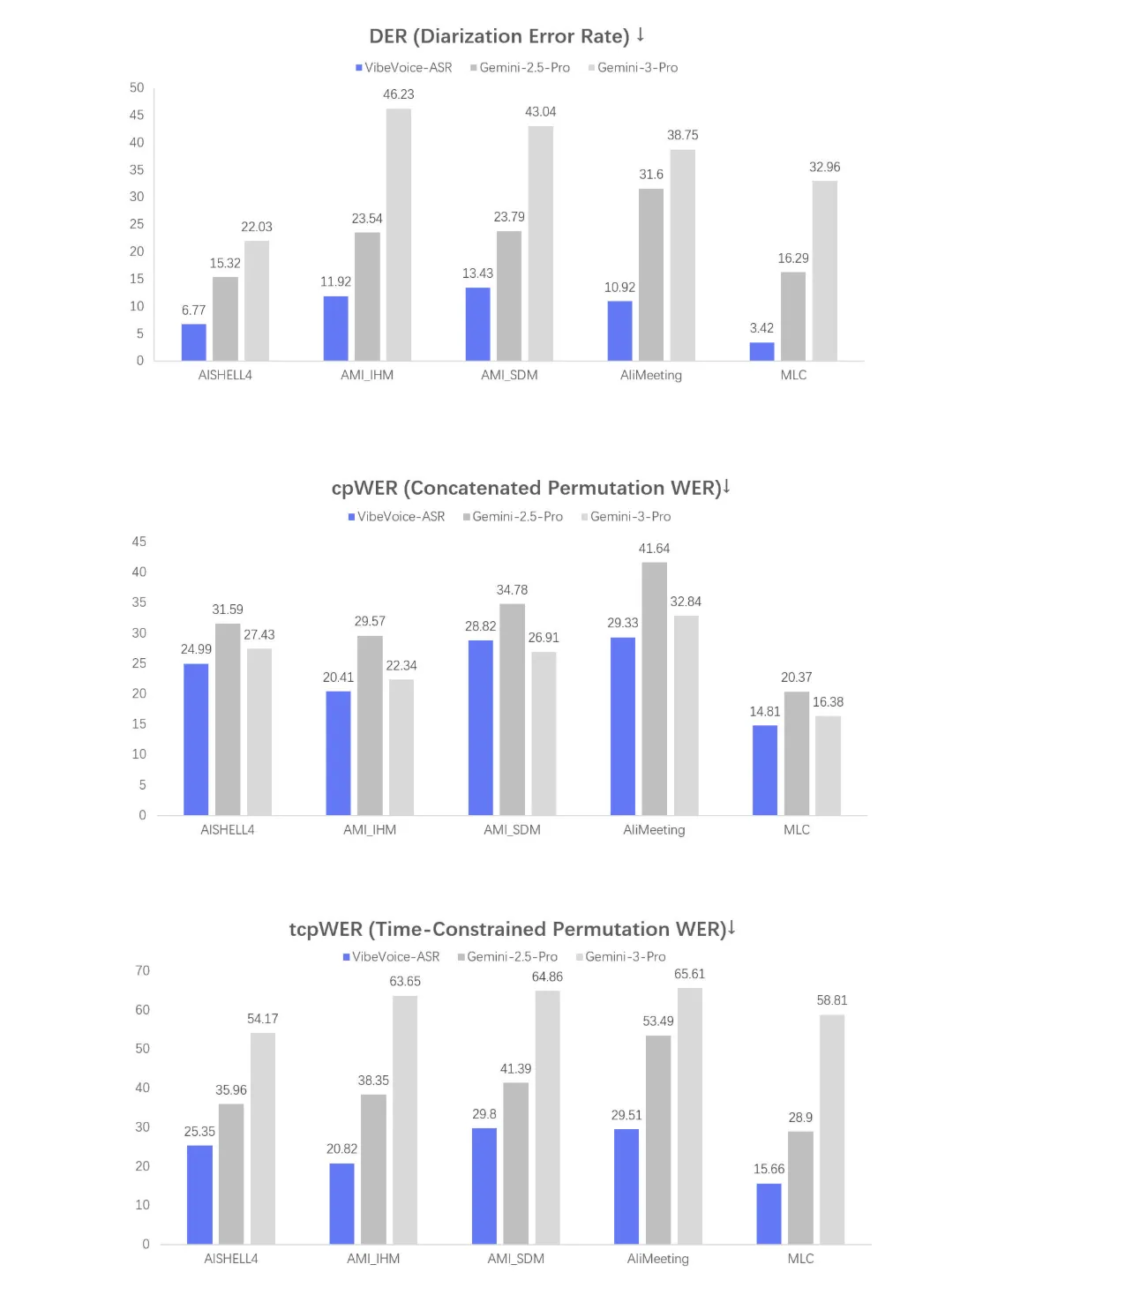
    Microsoft has released VibeVoice-ASR as part of the VibeVoice family of open source frontier voice AI models. VibeVoice-ASR is described as a unified speech-to-text model that can handle 60-minute long-form audio in a single pass and output structured transcriptions that encode Who, When, and What, with support for Customized Hotwords. VibeVoice sits in a single repository that hosts Text-to-Speech, real time TTS, and Automatic Speech Recognition models under an MIT license. VibeVoice uses continuous speech tokenizers that run at 7.5 Hz and a next-token diffusion framework where a Large Language Model reasons over text and dialogue and a diffusion head…

  • FlashLabs Researchers Release Chroma 1.0: A 4B Real Time Speech Dialogue Model With Personalized Voice Cloning

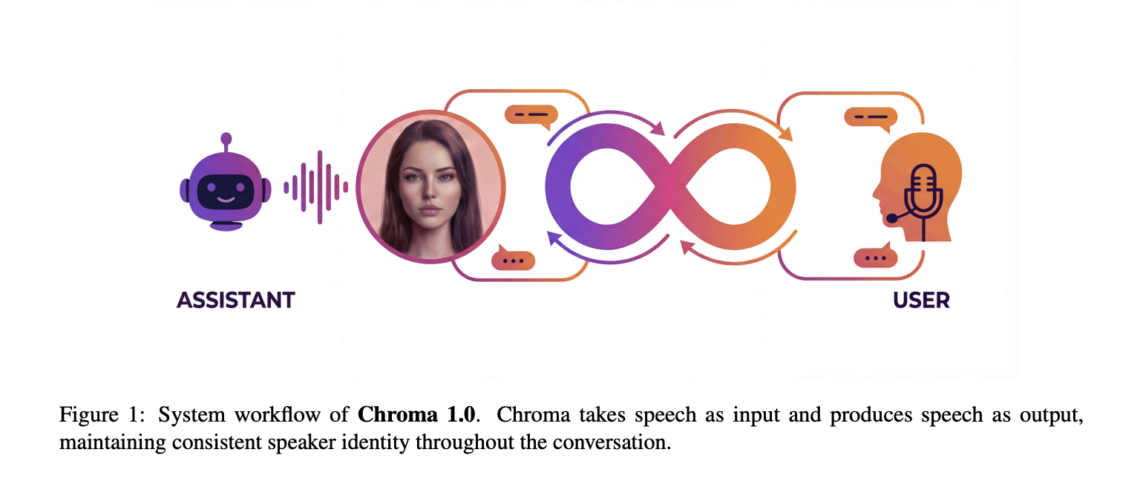
    Chroma 1.0 is a real time speech to speech dialogue model that takes audio as input and returns audio as output while preserving the speaker identity across multi turn conversations. It is presented as the first open source end to end spoken dialogue system that combines low latency interaction with high fidelity personalized voice cloning from only a few seconds of reference audio. The model operates directly on discrete speech representations rather than on text transcripts. It targets the same use cases as commercial real time agents, but with a compact 4B parameter dialogue core and a design that treats…

  • Inworld AI Releases TTS-1.5 For Realtime, Production Grade Voice Agents

    Inworld AI has introduced Inworld TTS-1.5, an upgrade to its TTS-1 family that targets realtime voice agents with strict constraints on latency, quality, and cost. TTS-1.5 is described as the number top ranked text to speech system on Artificial Analysis and is designed to be more expressive and more stable than prior generations while remaining suitable for large scale consumer deployments. Realtime latency for interactive agents TTS-1.5 focuses on P90 time to first audio latency, which is a critical metric for user perceived responsiveness. For TTS-1.5 Max, P90 time to first audio is below 250 ms. For TTS-1.5 Mini, P90…

  • How AutoGluon Enables Modern AutoML Pipelines for Production-Grade Tabular Models with Ensembling and Distillation

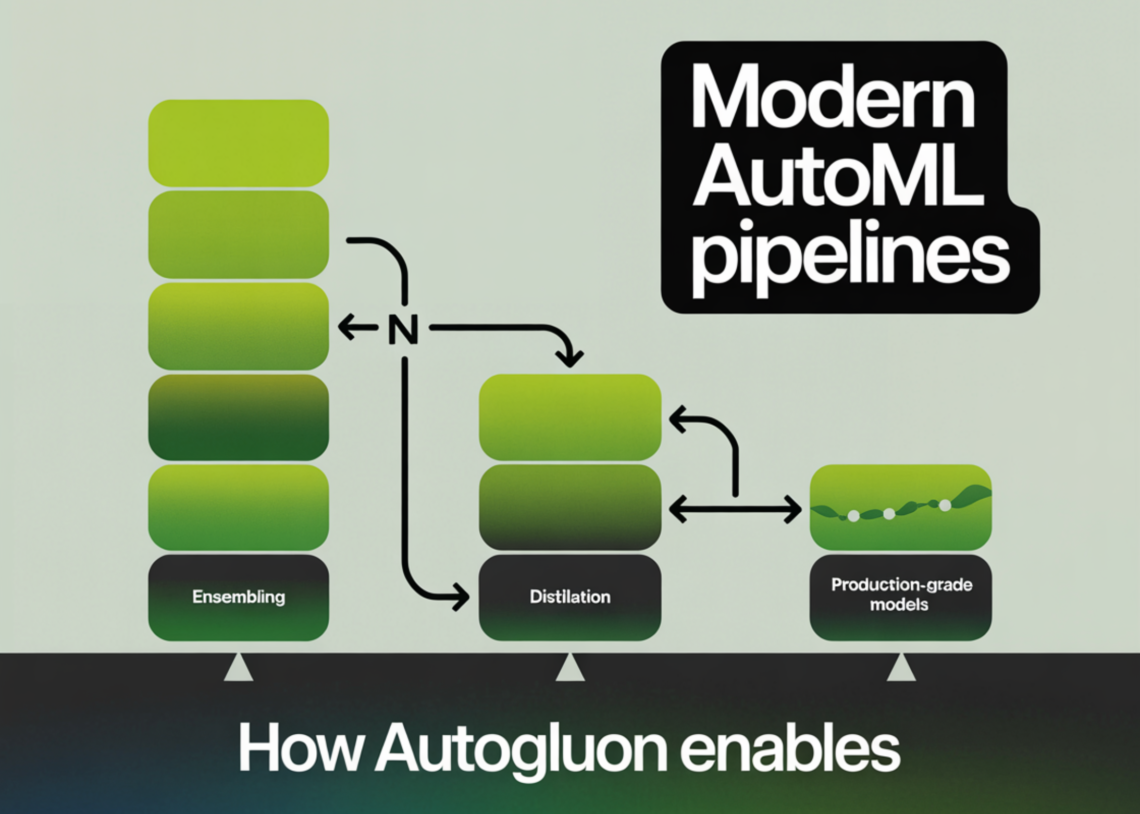
    In this tutorial, we build a production-grade tabular machine learning pipeline using AutoGluon, taking a real-world mixed-type dataset from raw ingestion through to deployment-ready artifacts. We train high-quality stacked and bagged ensembles, evaluate performance with robust metrics, perform subgroup and feature-level analysis, and then optimize the model for real-time inference using refit-full and distillation. Throughout the workflow, we focus on practical decisions that balance accuracy, latency, and deployability. Check out the FULL CODES here. !pip -q install -U "autogluon==1.5.0" "scikit-learn>=1.3" "pandas>=2.0" "numpy>=1.24" import os, time, json, warnings warnings.filterwarnings("ignore") import numpy as np import pandas as pd from sklearn.model_selection import train_test_split from…